About Wally
We left big tech to build the pipeline that writes the kernels.
Wally is a research-first inference lab. We build the pipeline behind the kernels that make consumer silicon fast, publish the numbers, and open-source the SDKs and infrastructure that carry that speed to every platform. Not a wrapper, all the way down.
Our approach
Research that ships.
Research is product
Every benchmark we publish runs on the same engine that powers production applications. NeuRT isn't a prototype - it's a C++ inference runtime that developers use today.
Hard systems problems
Memory-efficient model execution, co-scheduled multi-modal pipelines, and hardware-specific optimization for the Apple Neural Engine and Qualcomm Hexagon NPUs.
Open by default
When we claim a speed record, we show the numbers, the methodology, and the hardware configuration so others can reproduce and build on our work.
Beyond the device
The same choice, at a bigger scale.
NeuRT and QHexRT stay the foundation: kernels built for the silicon a user is already holding. Wally extends the same work upward, to frontier-scale open models for jobs that outgrow a laptop. The developer decides, request by request, where it runs. Hosted is a flag, never a fallback.
Founders
Built by engineers who ship at scale.
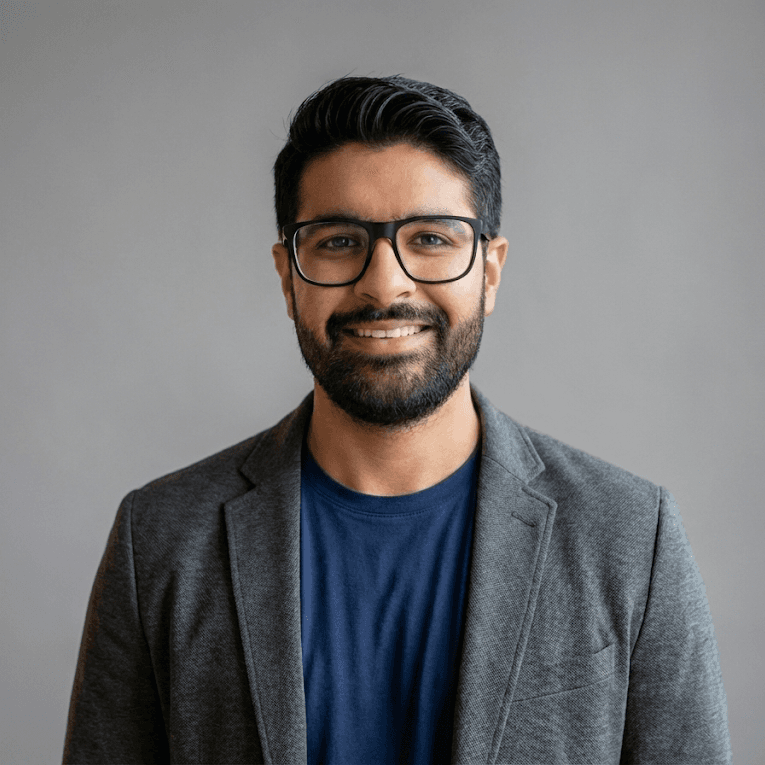
He leads the SDK and product layer.
Sanchit built mobile SDKs used by 50M+ people at Intuit, and watched every team hit the same wall: cloud AI was too slow, too expensive and too fragile for real products. He left to fix it. On-device deployment should feel like a cloud API call, across Swift, Kotlin, React Native and Flutter.
He leads the engine research and the control plane.
Shubham spent years on infrastructure at Microsoft Azure and AWS, systems that had to be fast, reliable and globally distributed. He applies that discipline to NeuRT, building the agentic pipeline that writes and validates kernels for the Apple Neural Engine.