Wally
Home
ResearchNews10.3K
Talk to usLogin
Y Combinator

Backed by Y Combinator

Engineering notes

From every layer of the stack.

AllQHexRT2MetalRT4SDKs3Agents2Voice2
MetalRT Now Does Speech-to-Speech. 1.52x Faster Than mlx-audio.
MetalRT·March 15, 2026

MetalRT Now Does Speech-to-Speech. 1.52x Faster Than mlx-audio.

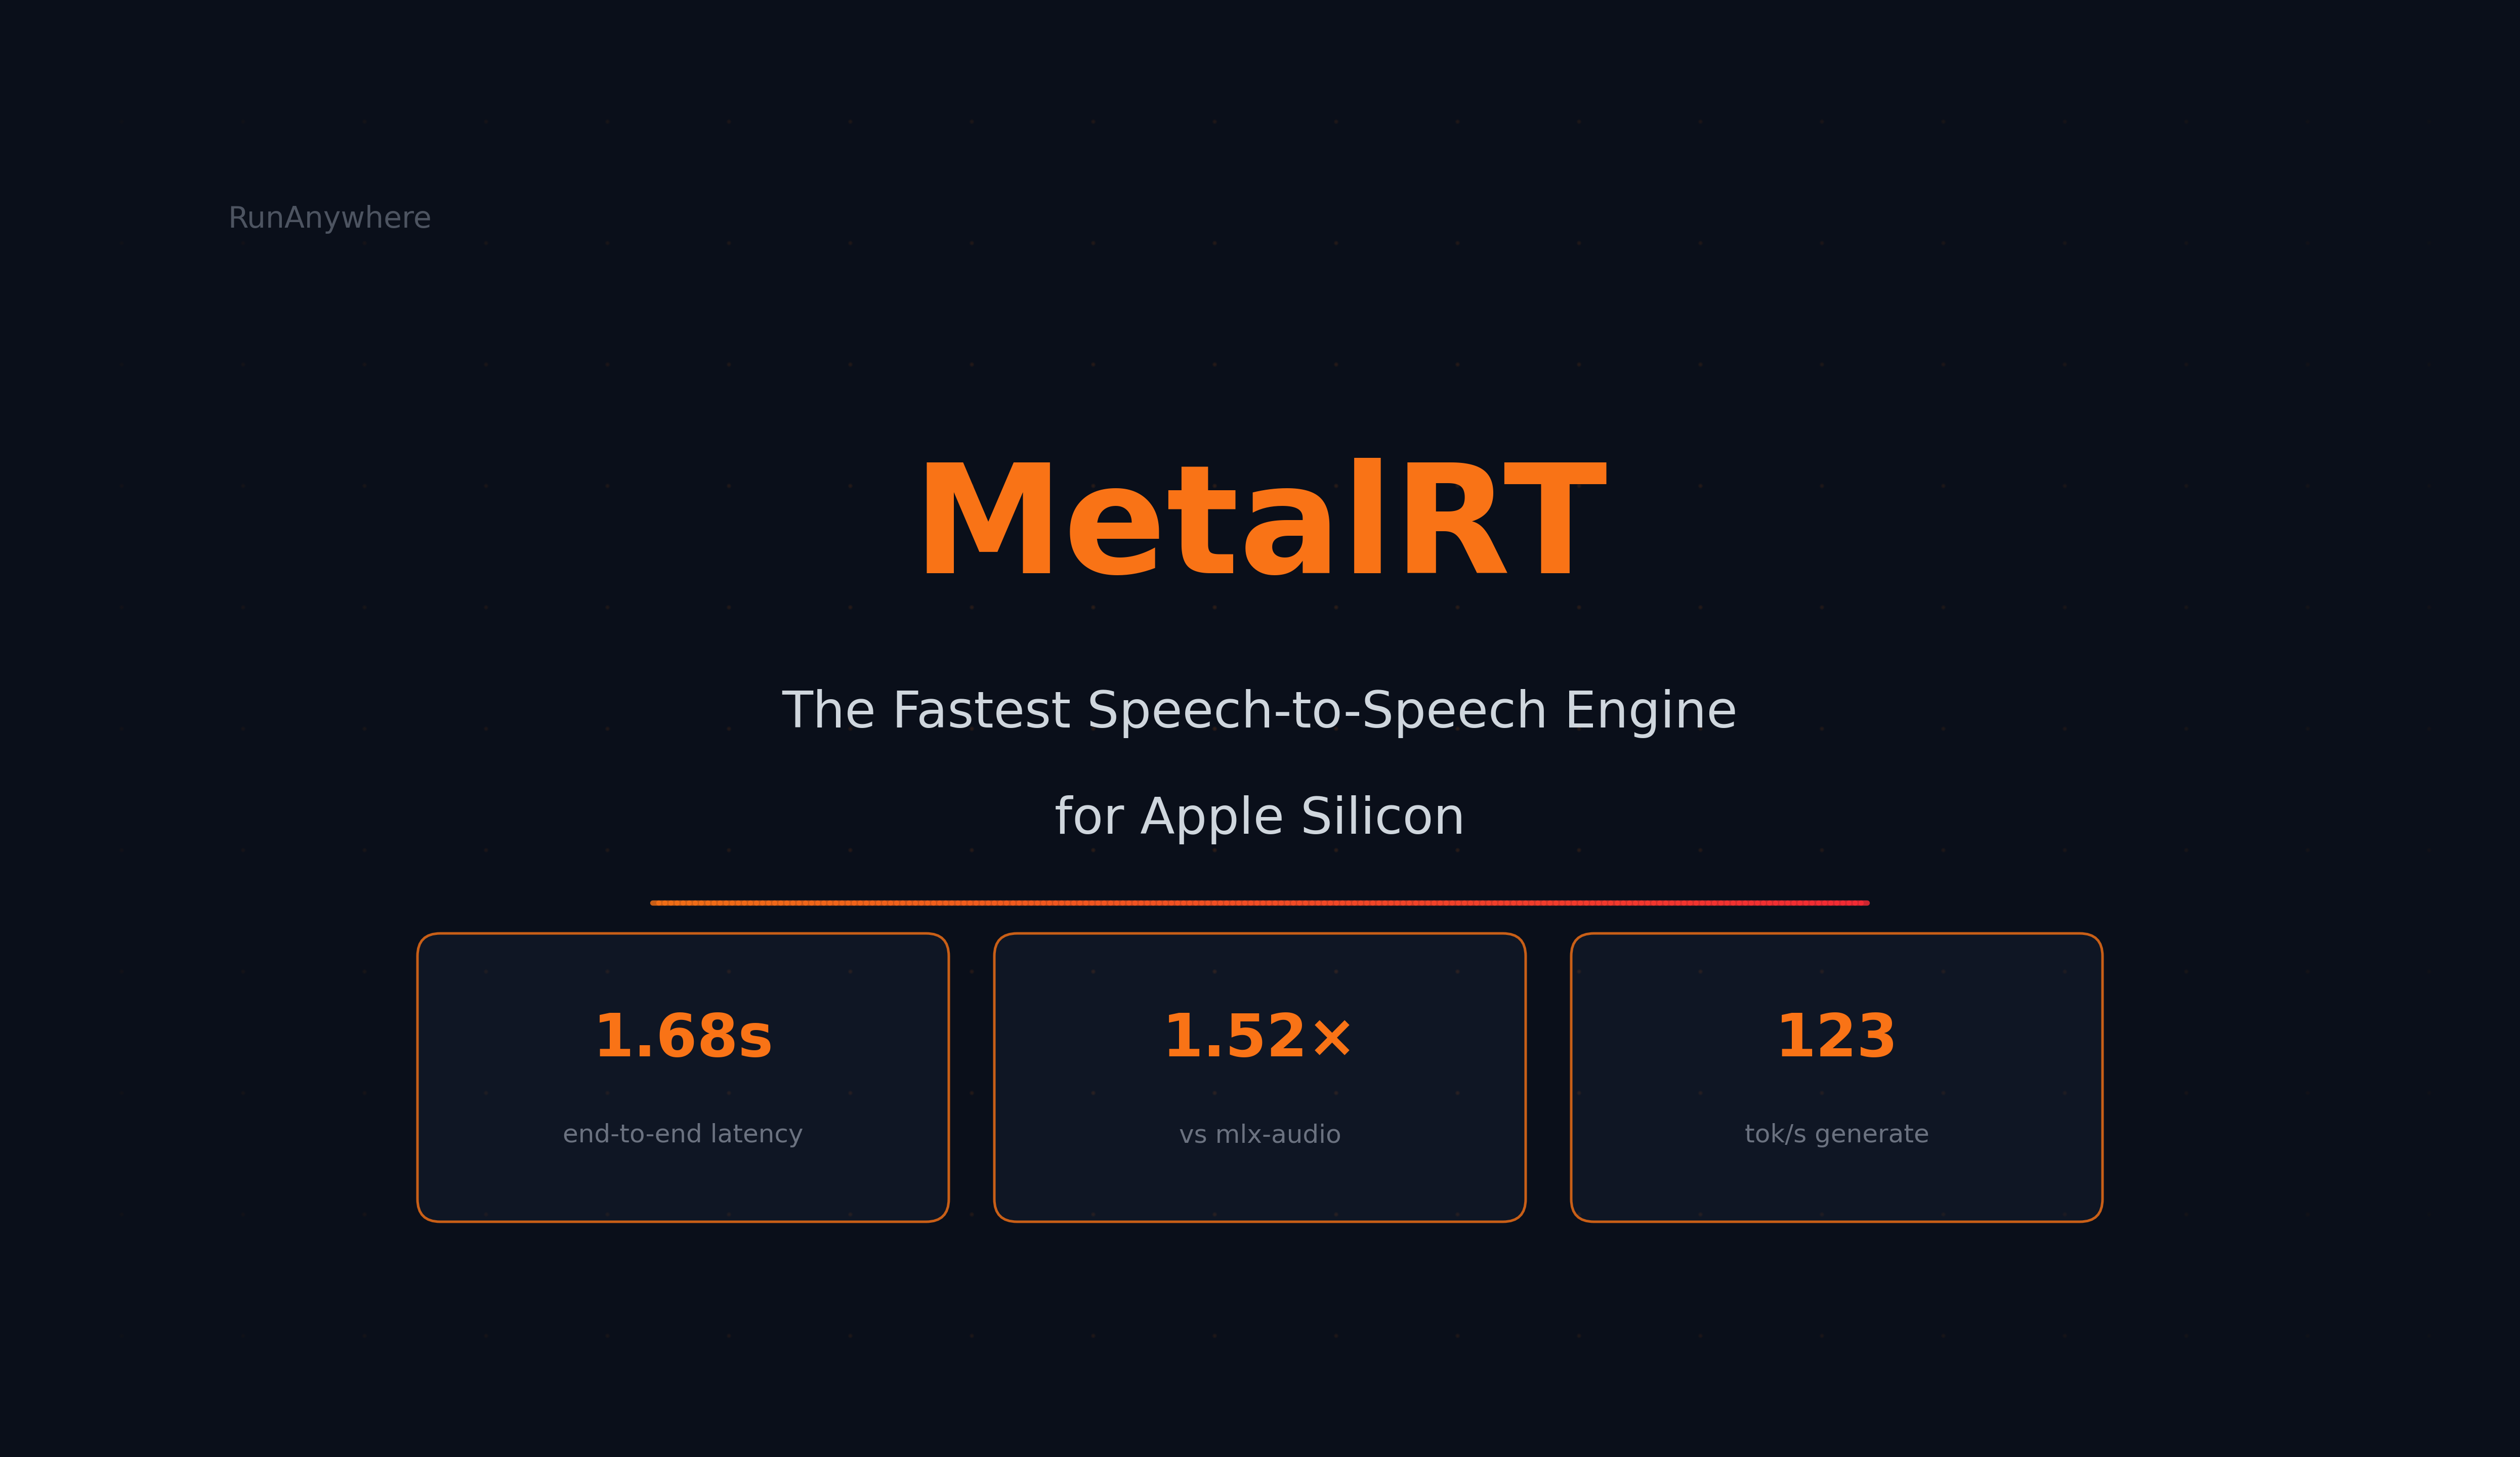
MetalRT adds native speech-to-speech support. 1.68s end-to-end latency, 123 tok/s generation throughput, 1.52x faster than mlx-audio on a single M4 Max.
MetalRT Now Runs Vision Language Models. Fastest on Apple Silicon.
MetalRT·March 13, 2026

MetalRT Now Runs Vision Language Models. Fastest on Apple Silicon.

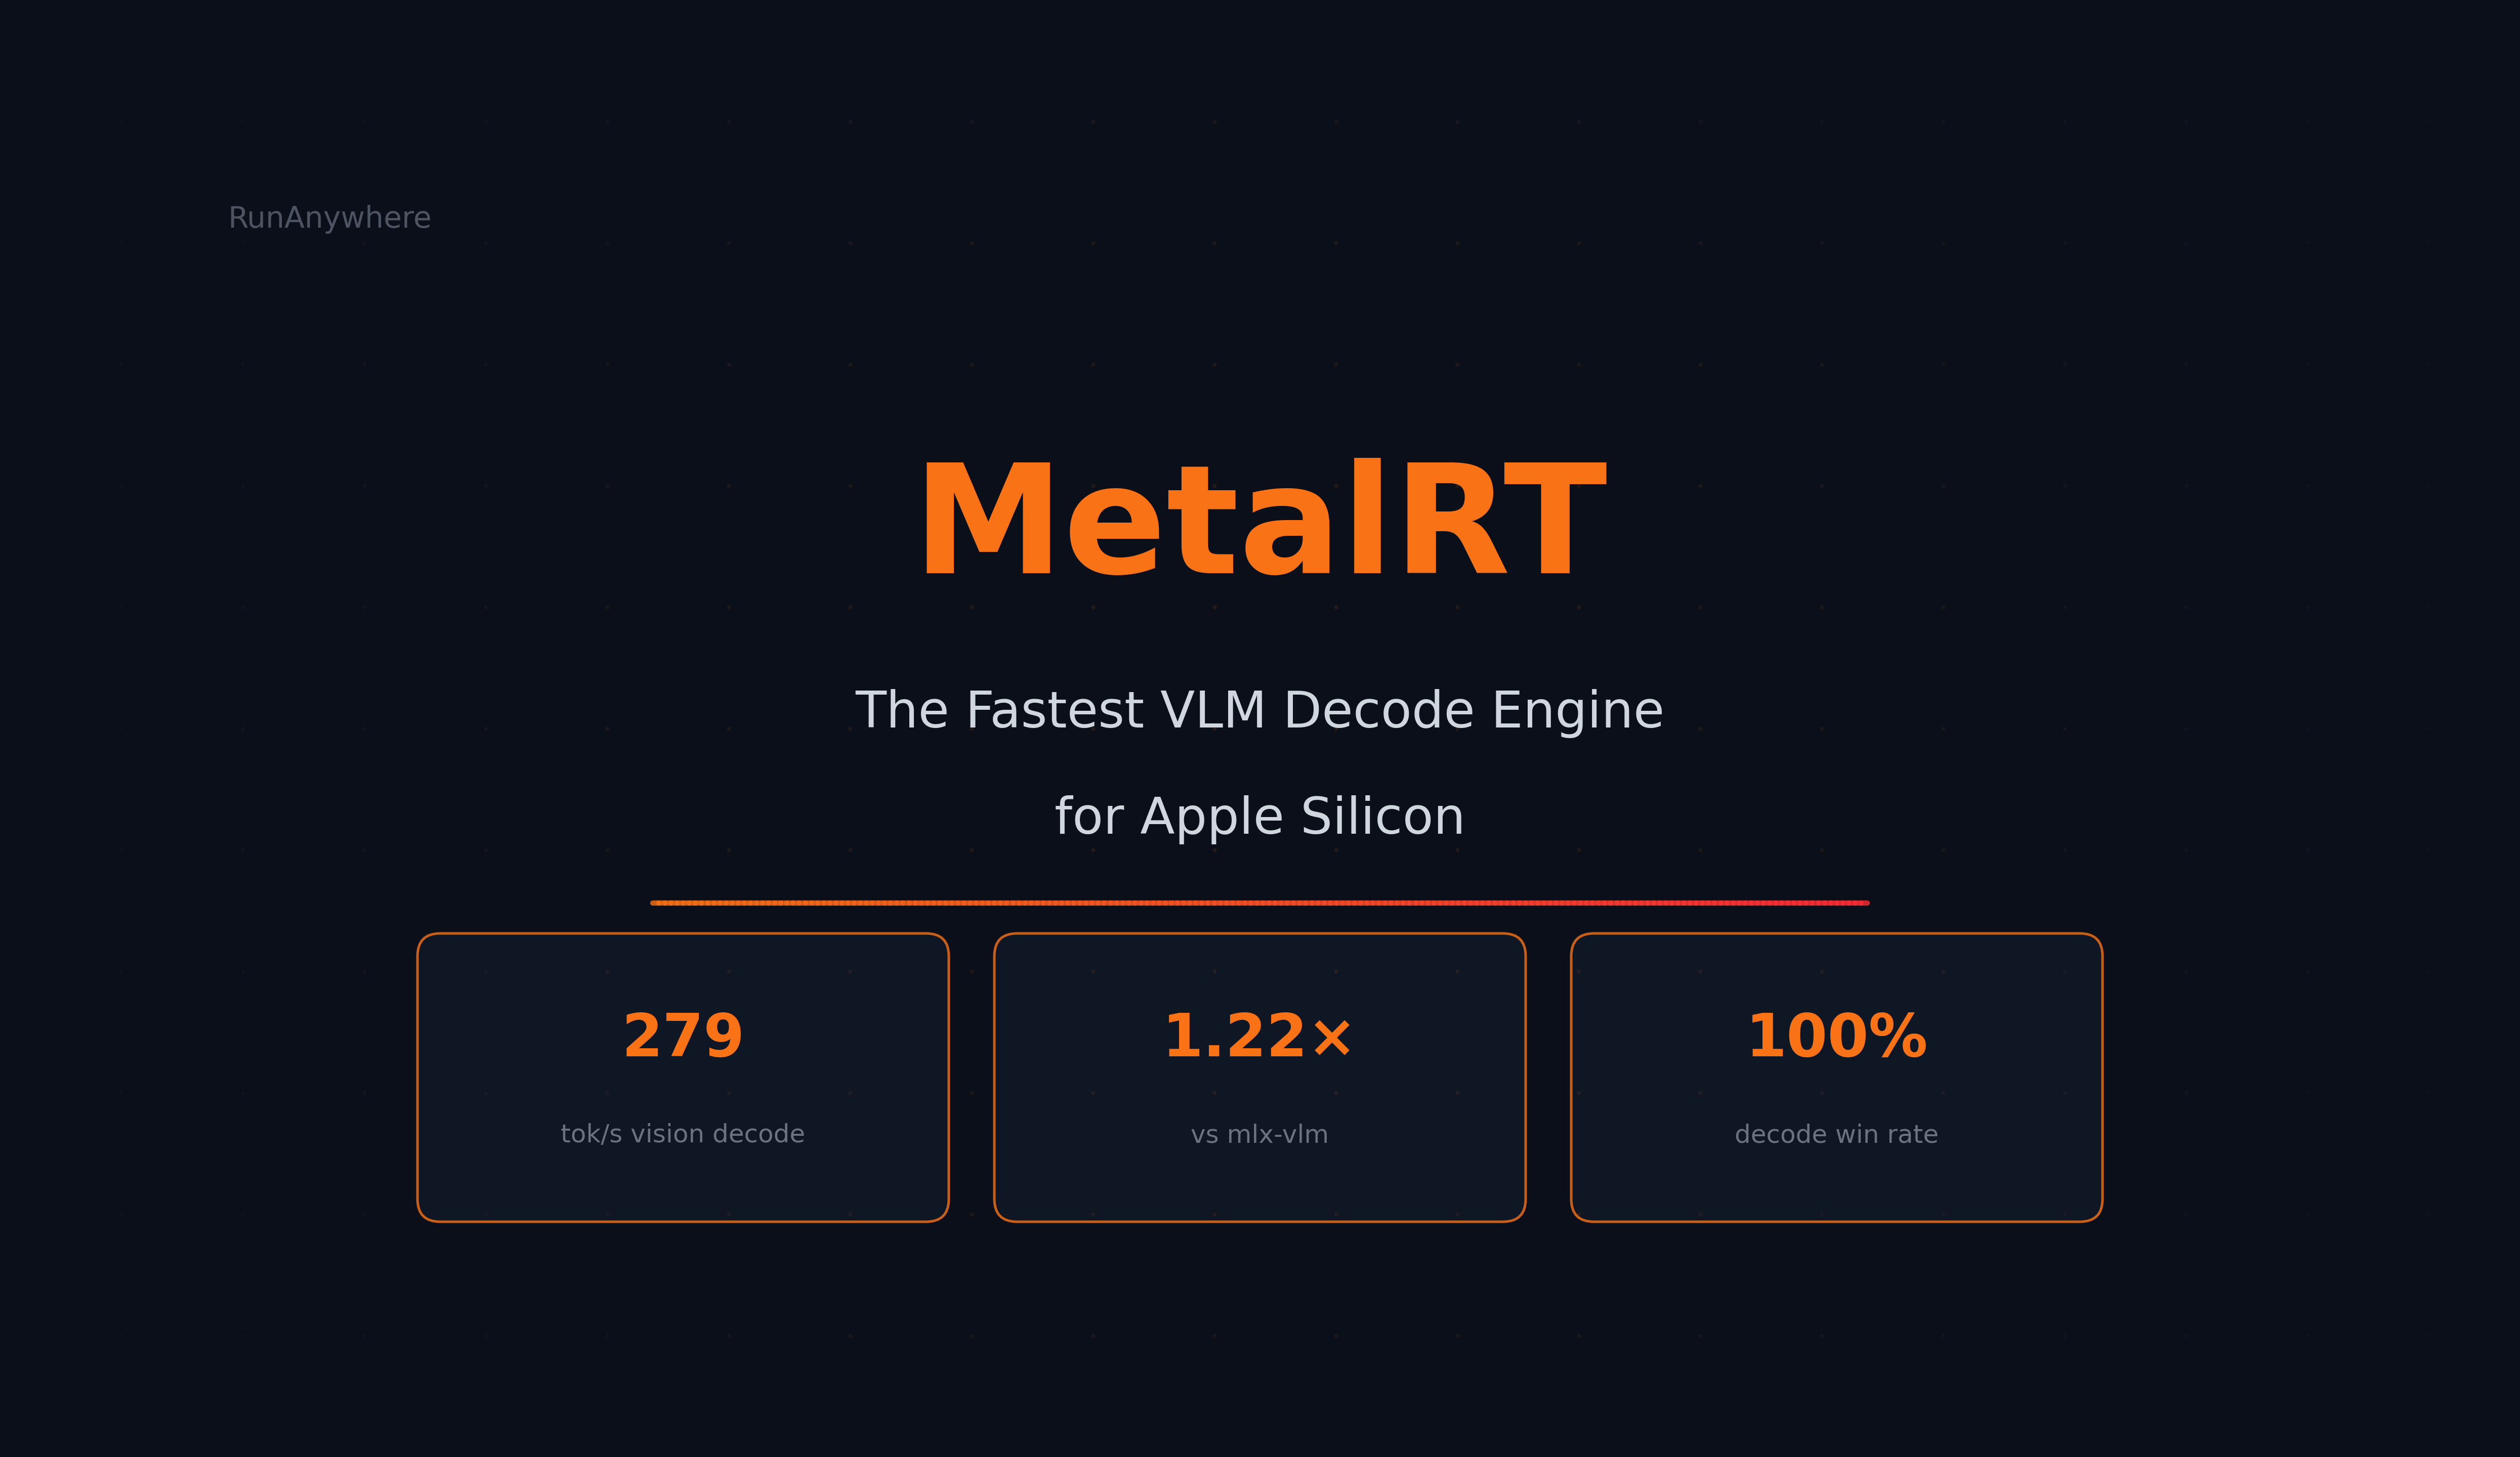
MetalRT adds VLM support and wins every decode benchmark. 279 tok/s vision decode, 92ms time-to-output, 1.22x faster than mlx-vlm across all resolutions on a single M4 Max.
MetalRT: The First Complete AI Inference Engine for Apple Silicon. Now with Speech.
MetalRT·March 9, 2026

MetalRT: The First Complete AI Inference Engine for Apple Silicon. Now with Speech.

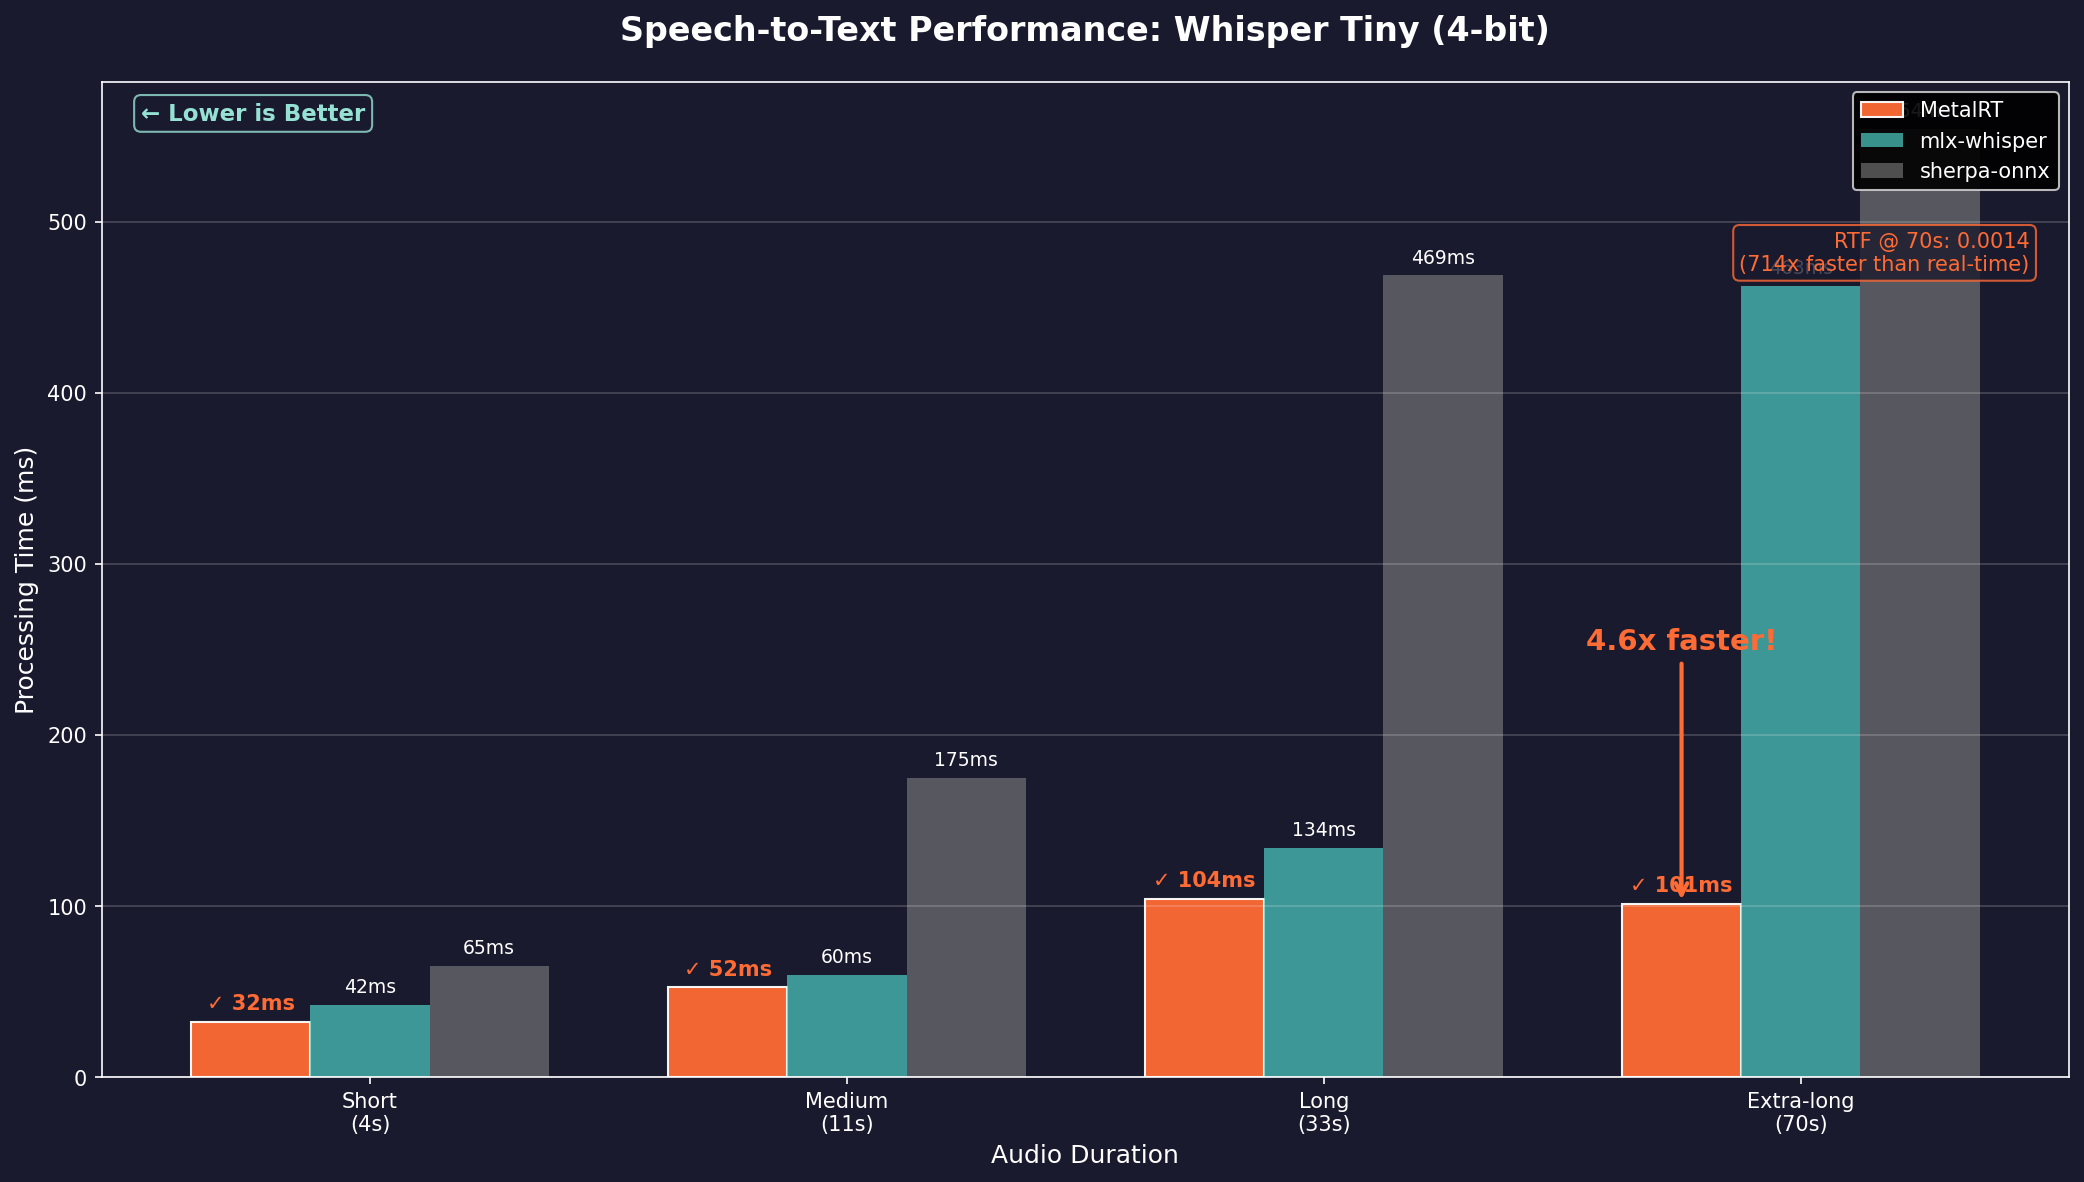
MetalRT becomes the first inference engine to handle LLMs, Speech-to-Text, and Text-to-Speech on Apple Silicon. 101ms to transcribe 70 seconds of audio. 178ms to synthesize speech. 4.6x faster than Apple MLX.
We Built the Fastest LLM Decode Engine for Apple Silicon. Here Are the Numbers.
MetalRT·March 3, 2026

We Built the Fastest LLM Decode Engine for Apple Silicon. Here Are the Numbers.

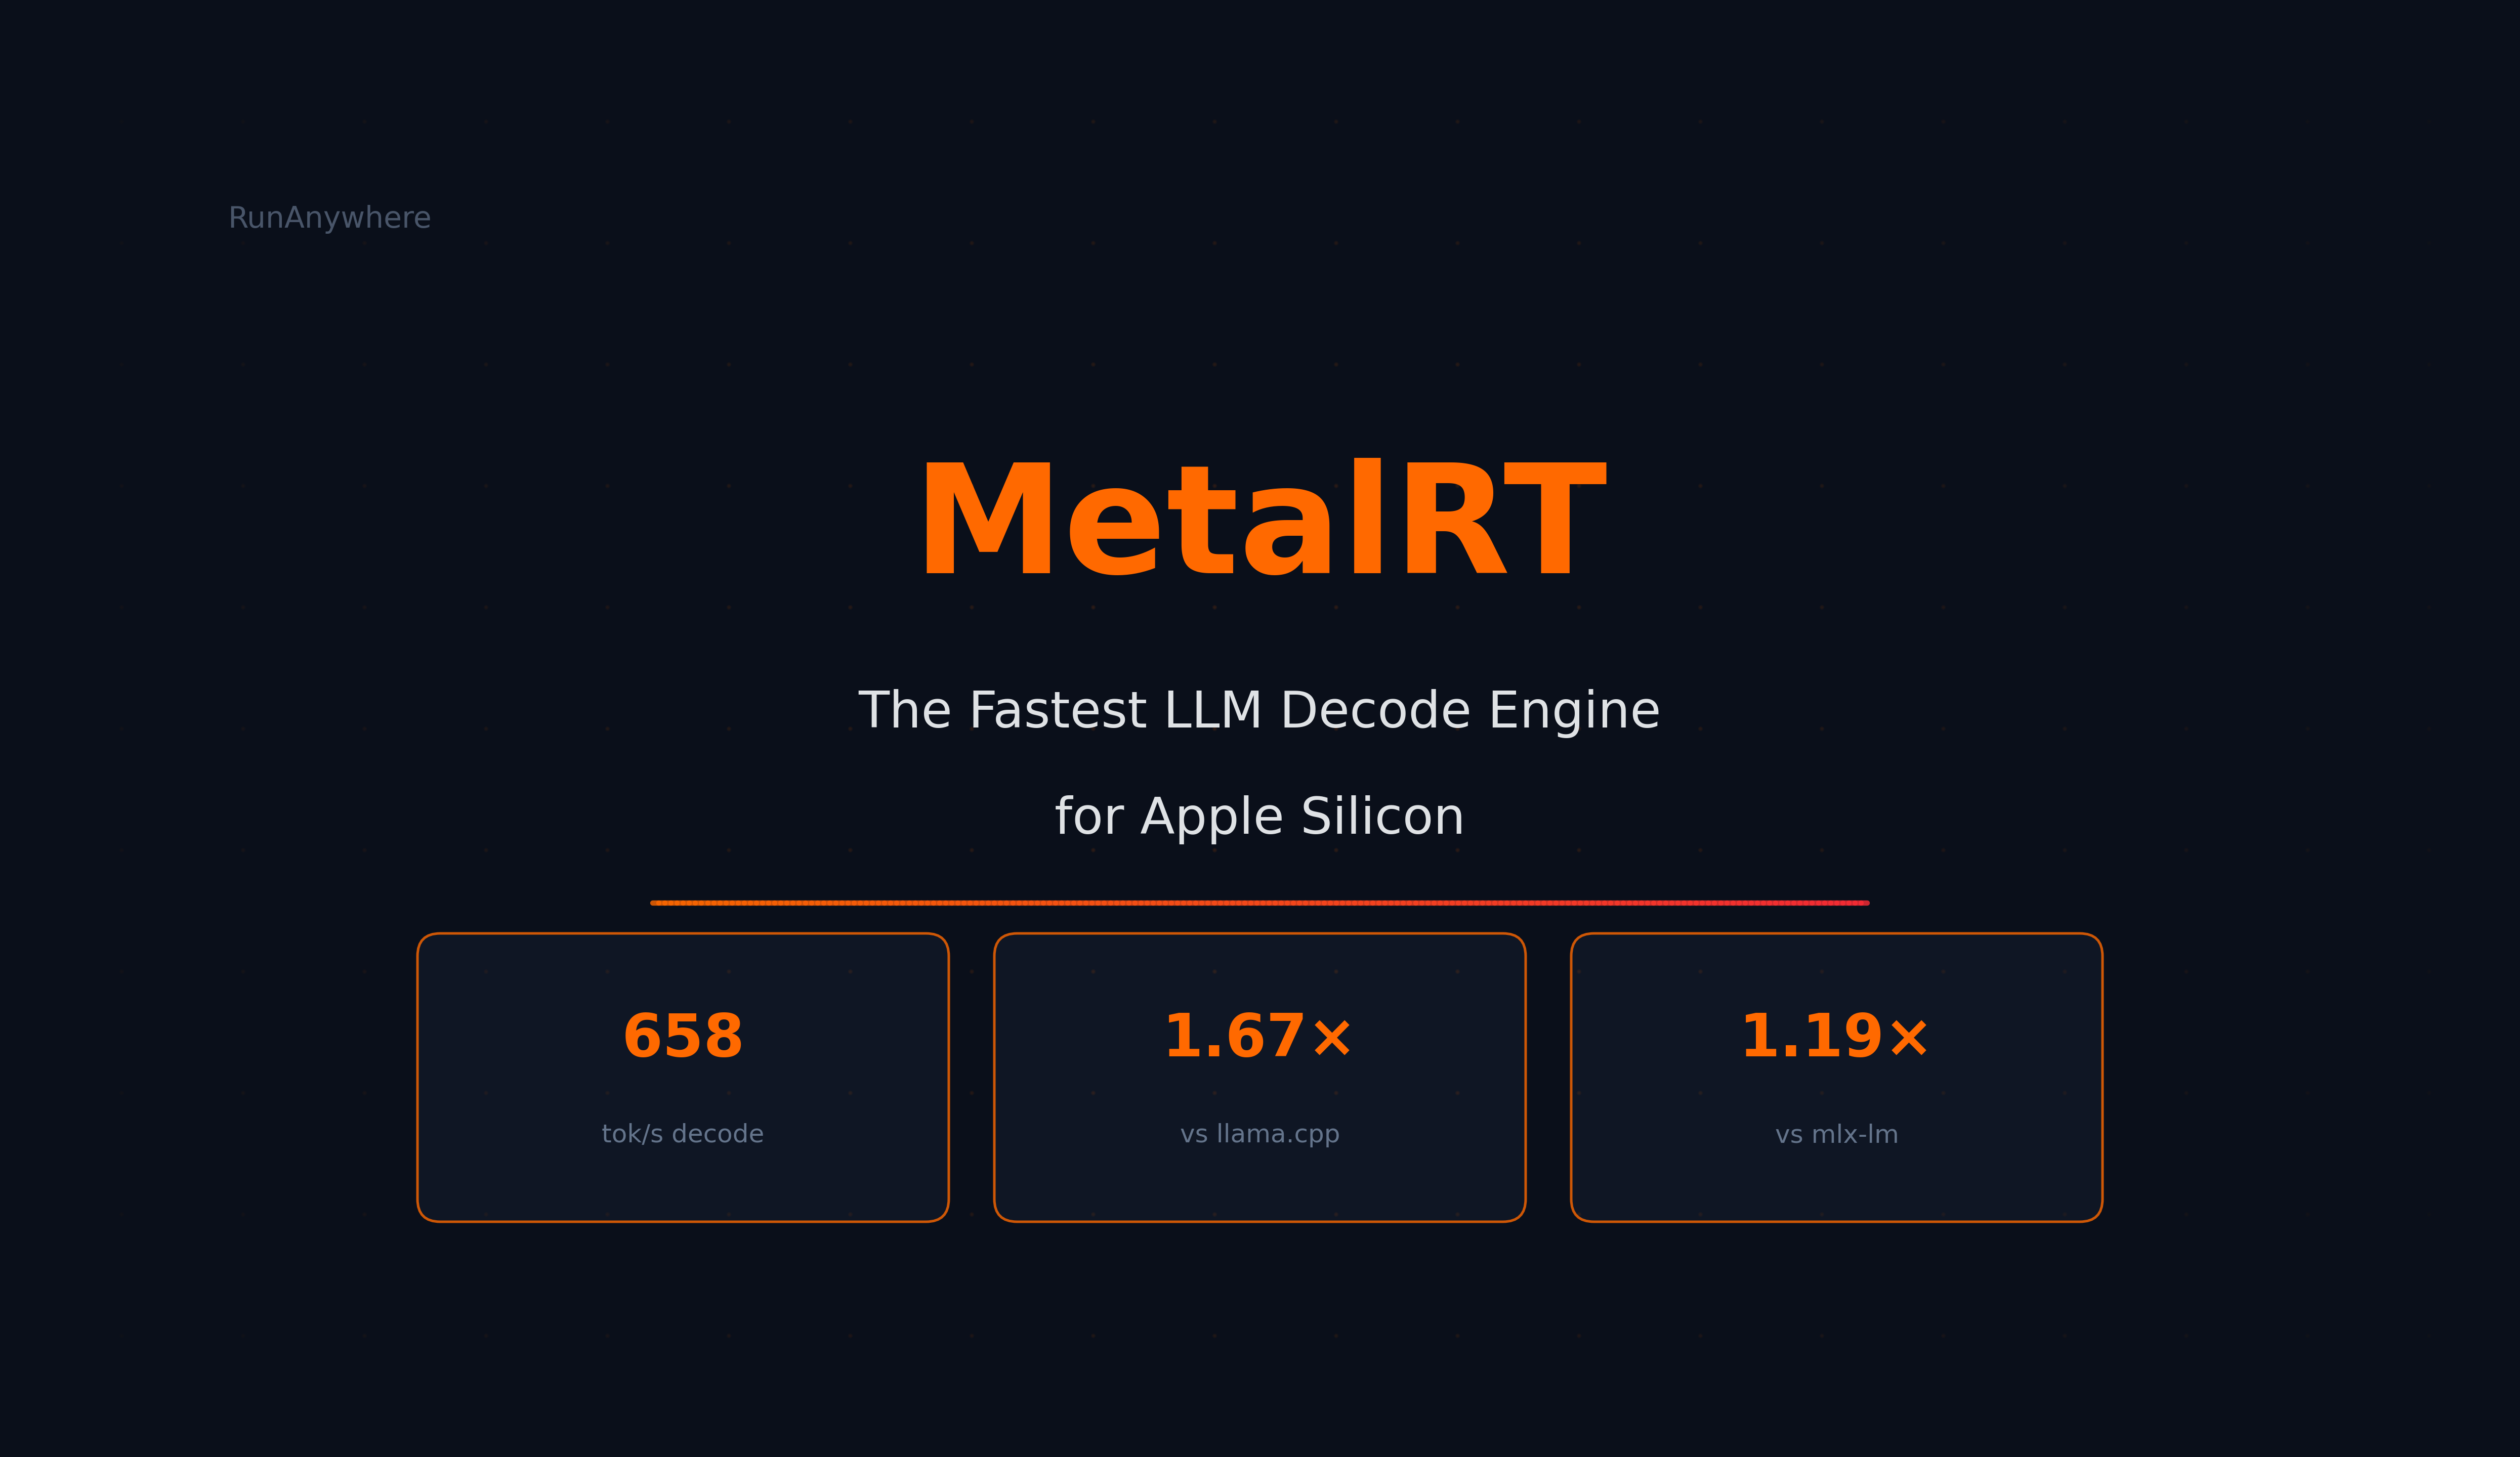
MetalRT delivers 658 tok/s decode and 6.6ms time-to-first-token, winning decode on 3 of 4 models we tested on a single M4 Max.

Wally

Wally hosted inference, local neural accelerators, and open-source SDKs from one inference lab.

Wally

  • Overview
  • Documentation
  • Console login

Developers

  • NeuRT
  • QHexRT
  • Local SDKs
  • GitHub

Research

  • Publications
  • Engineering blog
  • Inference Radar

Company

  • About
  • Press
  • Talk to us

© 2026 Wally, Inc.

  • Terms
  • Privacy
  • Refunds
  • Acceptable use