Wally
Home
ResearchNews10.3K
Talk to usLogin
Y Combinator

Backed by Y Combinator

Engineering notes

From every layer of the stack.

AllQHexRT2MetalRT4SDKs3Agents2Voice2
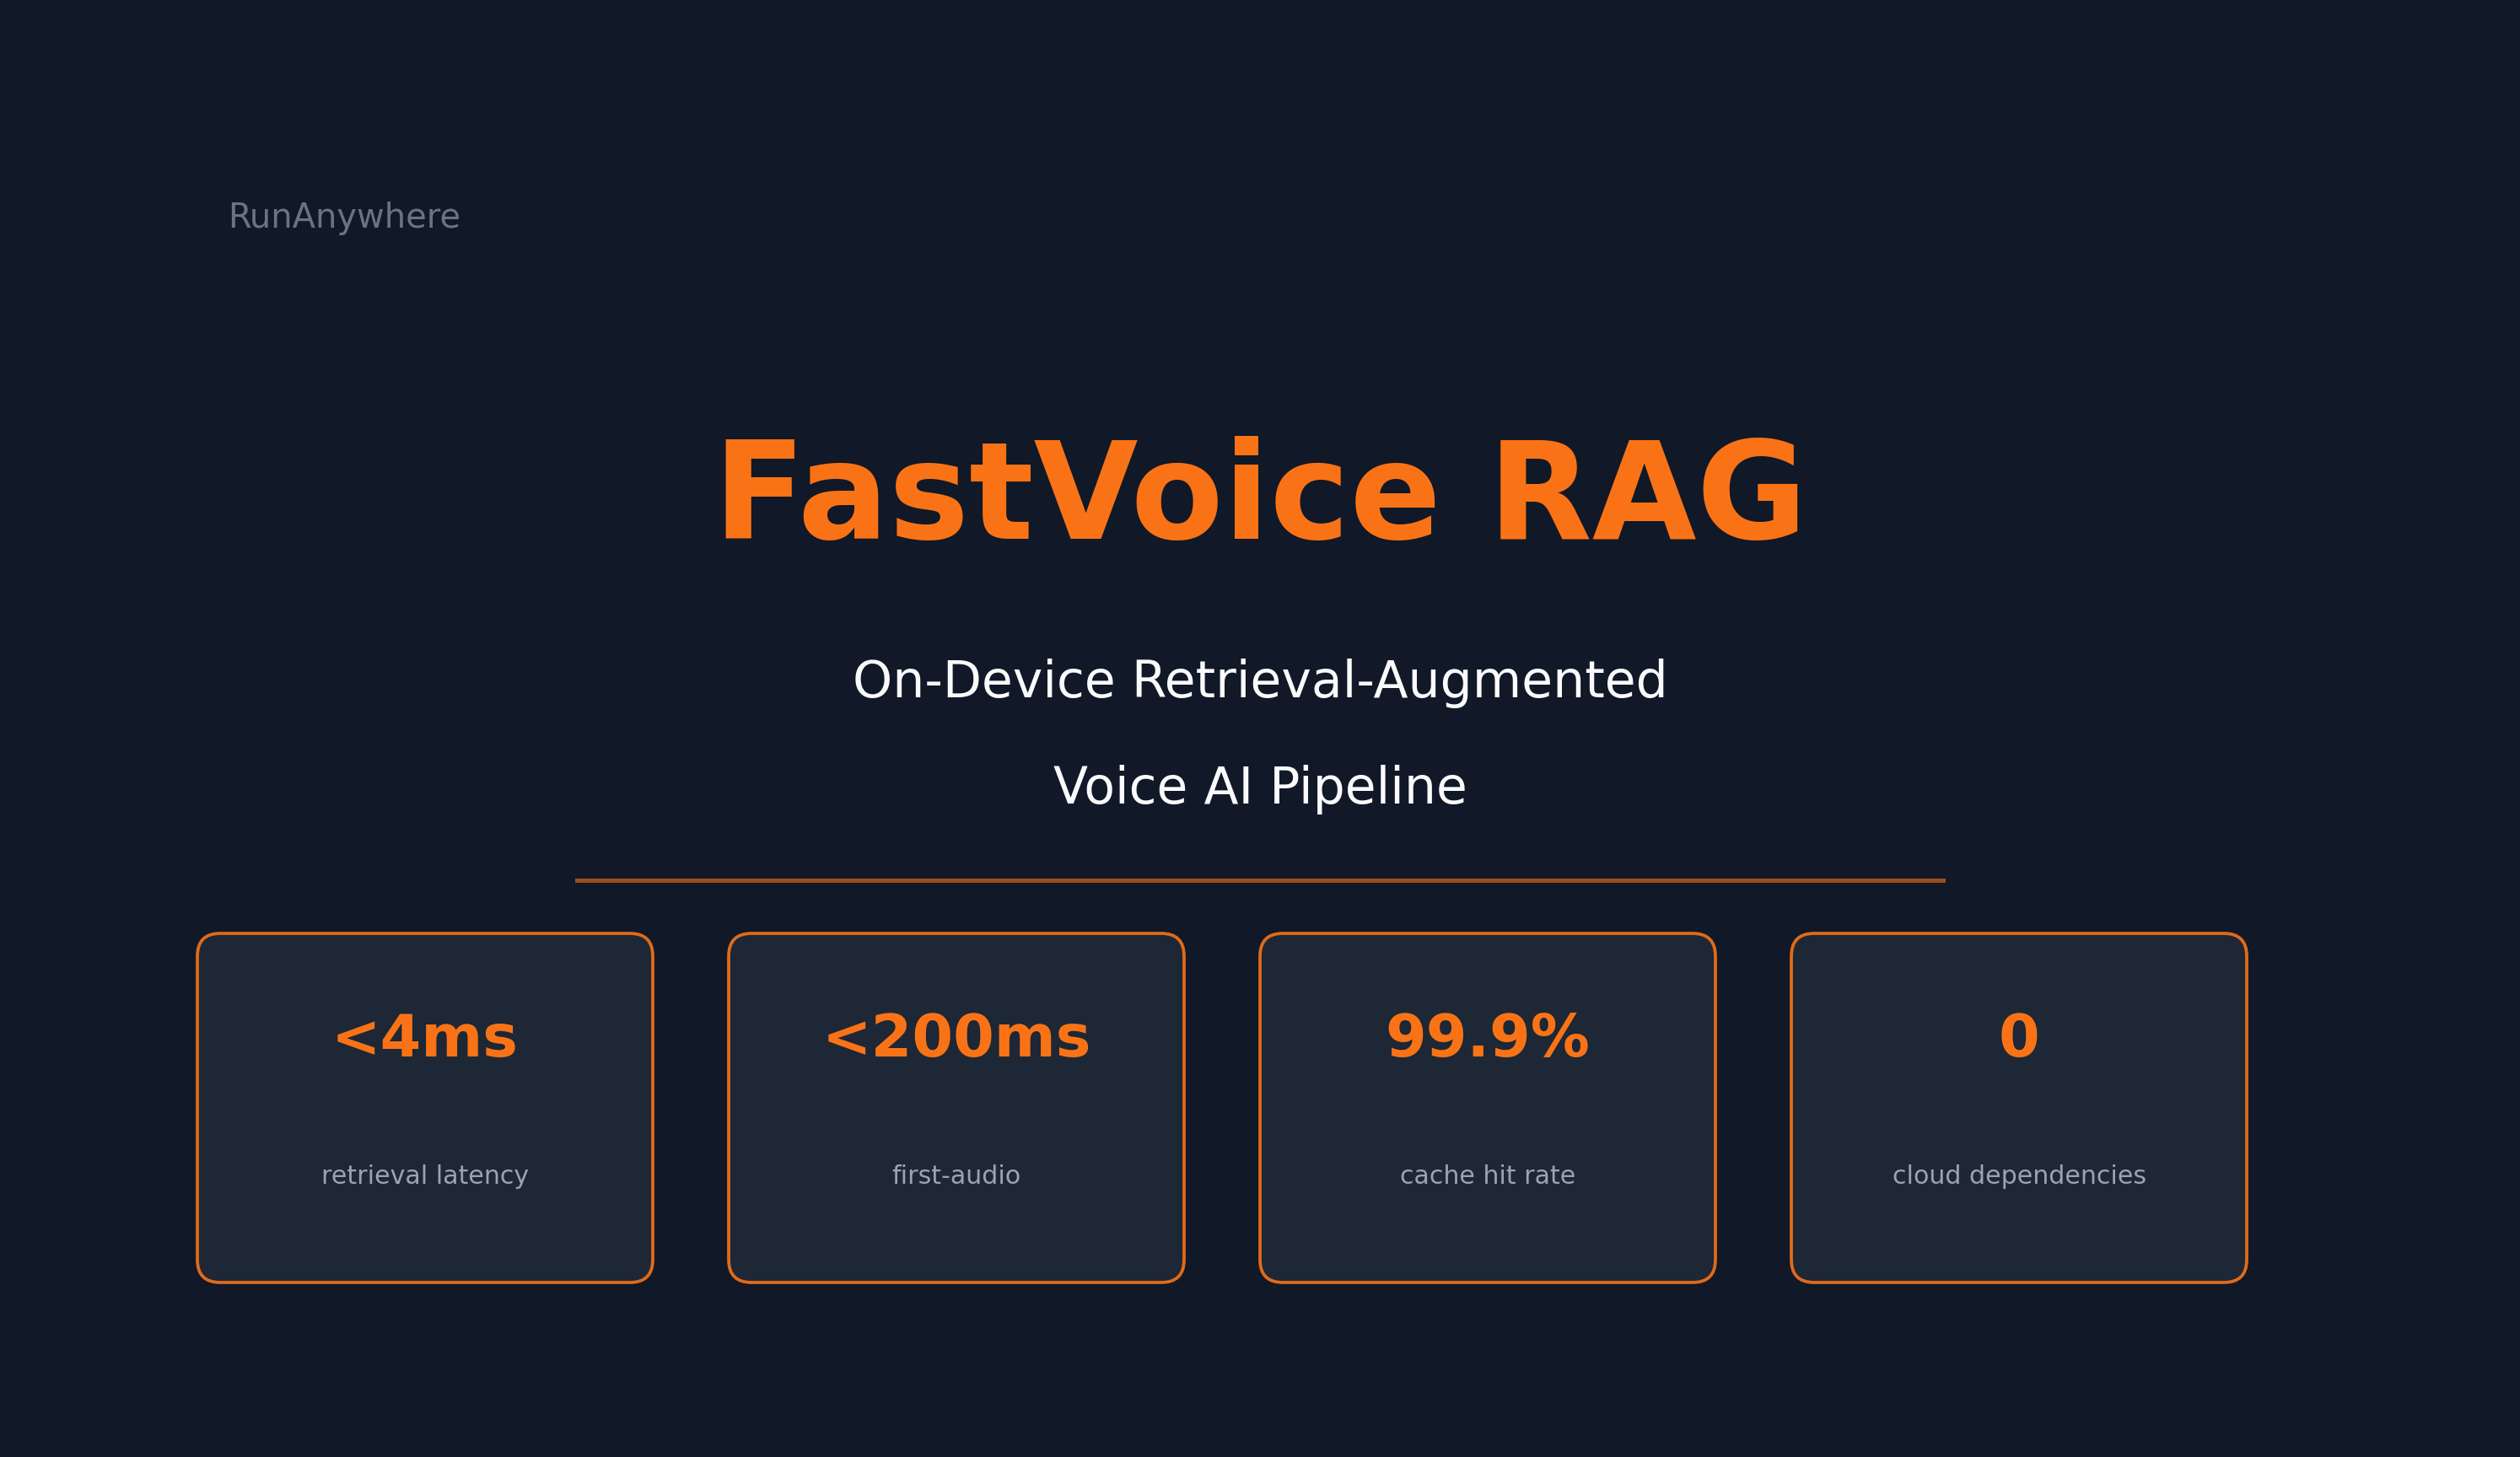
FastVoice RAG: Sub-200ms Voice AI with Retrieval-Augmented Generation, Entirely On-Device
Voice·February 24, 2026

FastVoice RAG: Sub-200ms Voice AI with Retrieval-Augmented Generation, Entirely On-Device

We added hybrid retrieval (BM25 + vector search) to our on-device voice pipeline. Retrieval adds less than 4ms. The real cost is LLM prefill — but word-level flushing absorbs it. Sub-200ms first-audio on 5,016 chunks with zero cloud dependencies.
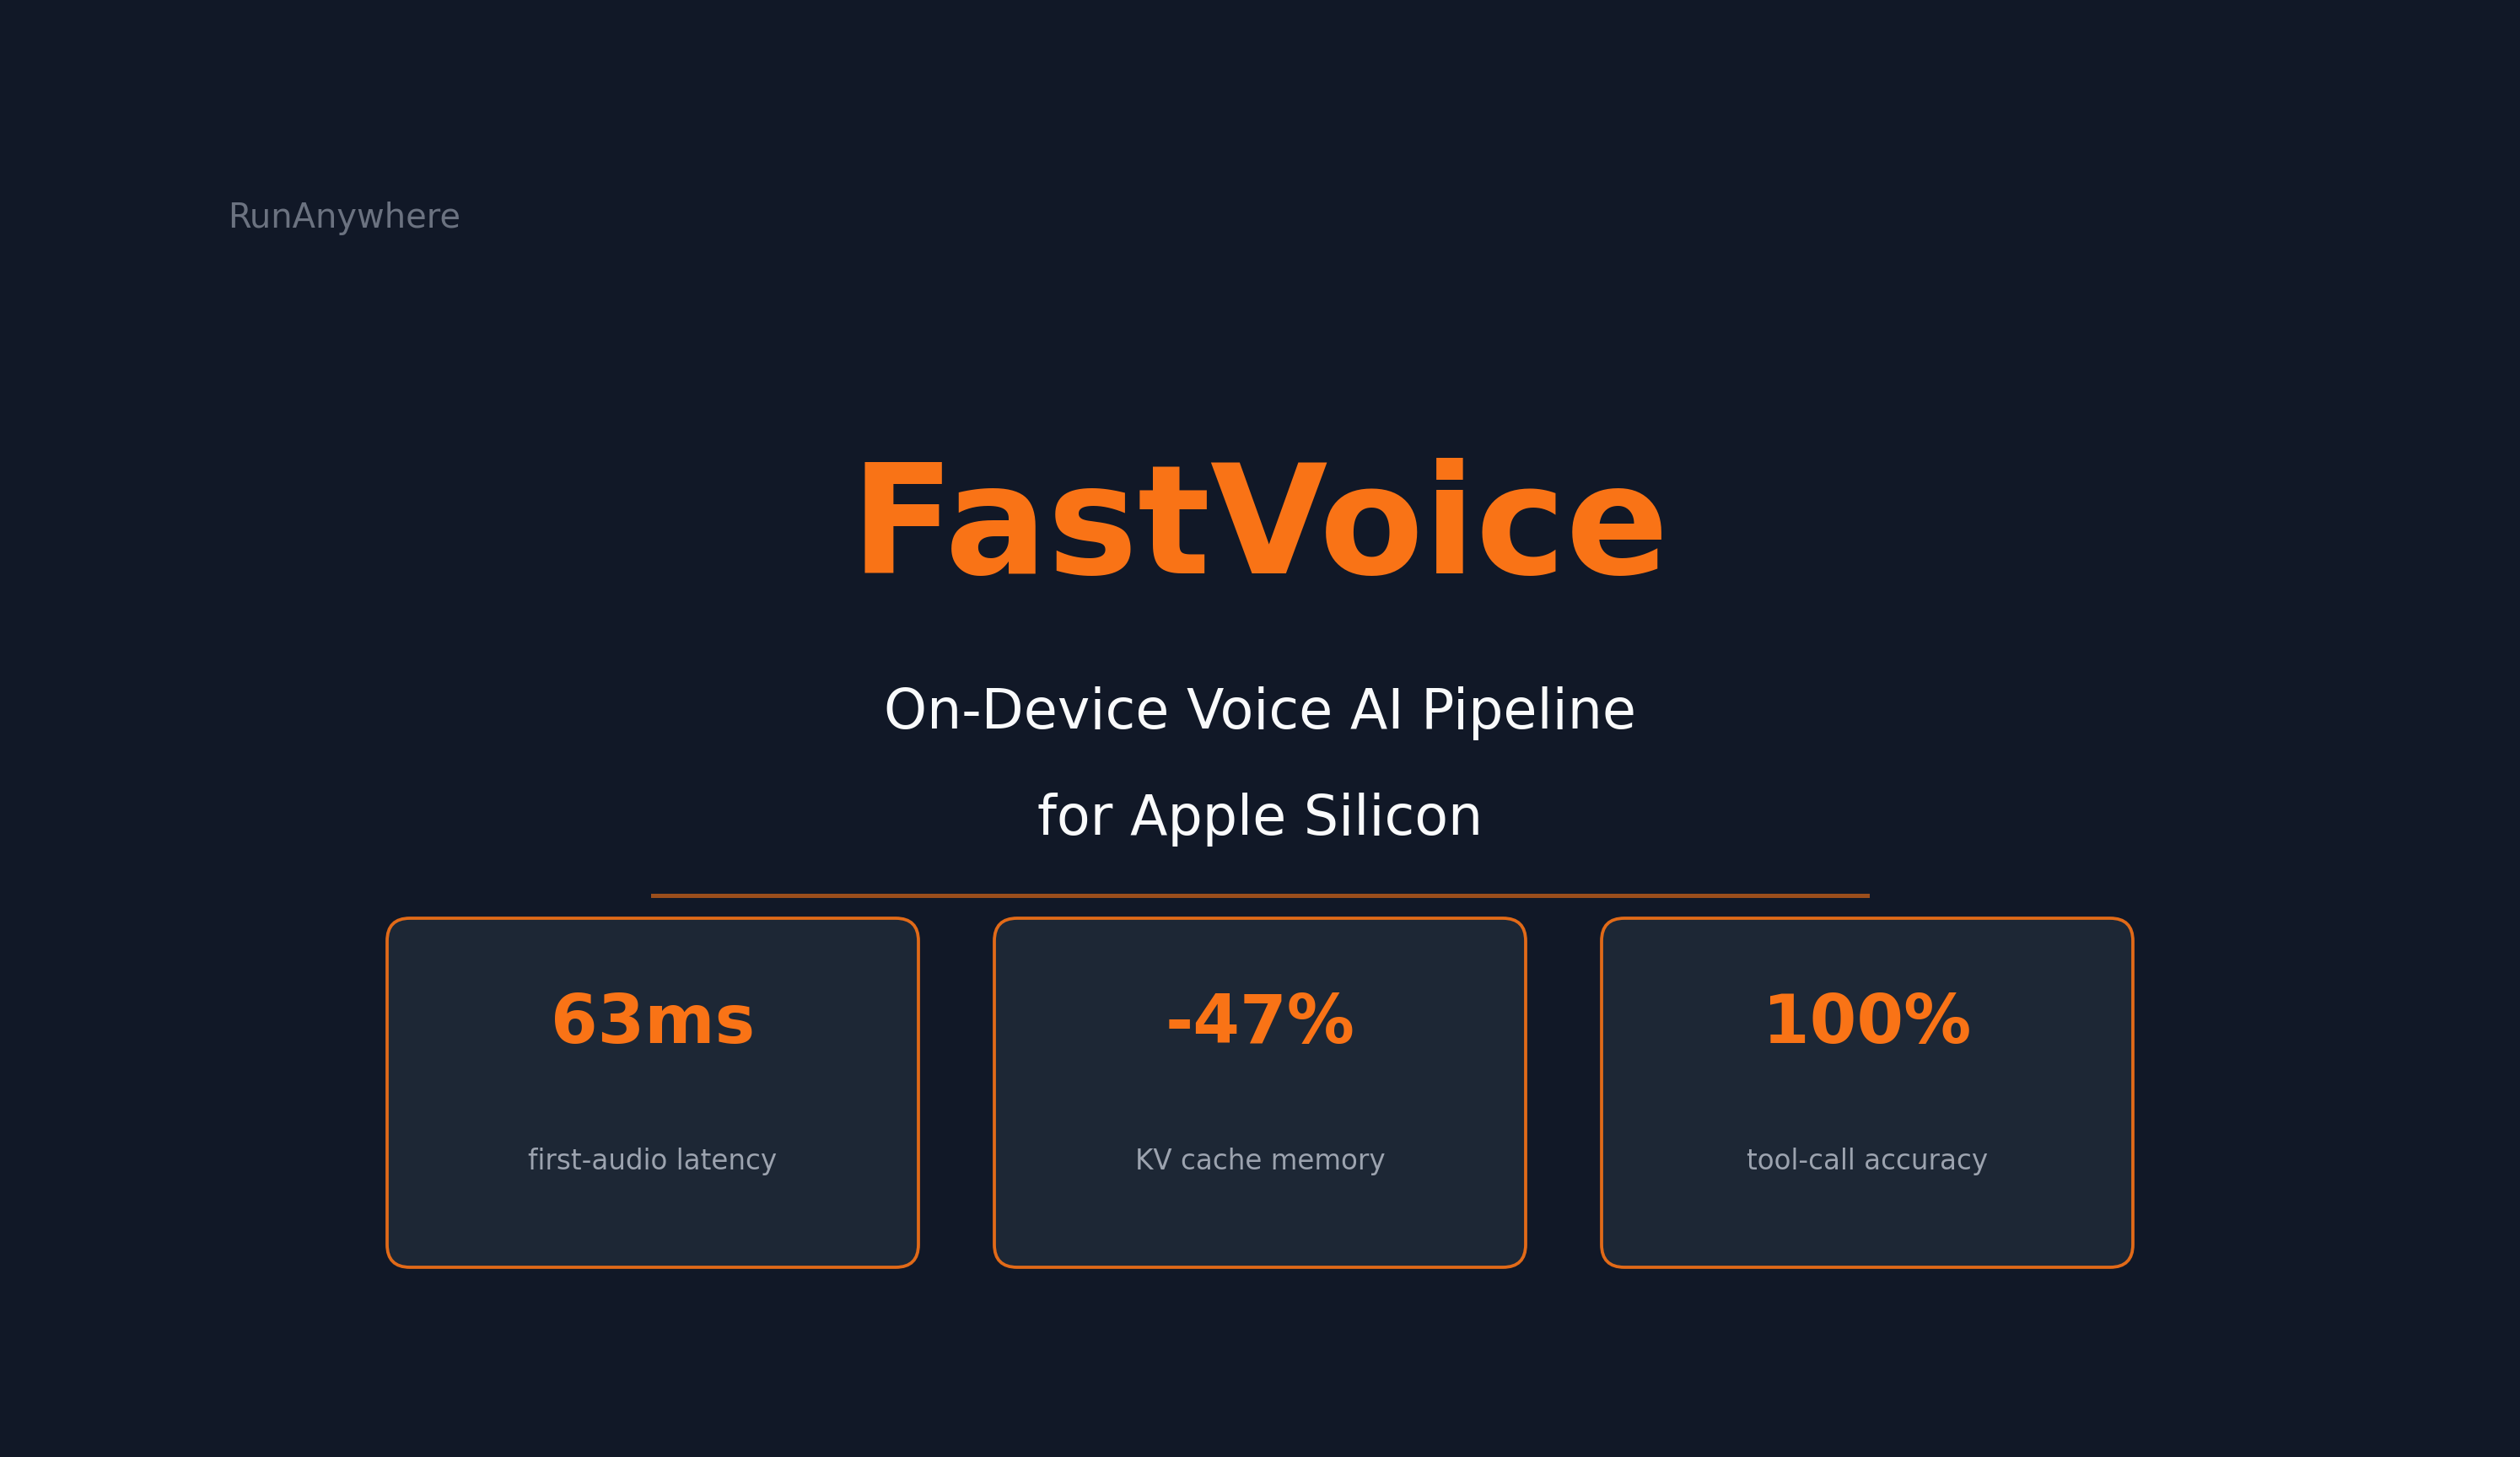
FastVoice: 63ms First-Audio Latency for On-Device Voice AI on Apple Silicon
Voice·February 22, 2026

FastVoice: 63ms First-Audio Latency for On-Device Voice AI on Apple Silicon

FastVoice achieves 63ms first-audio latency — well under the 200ms perceptual threshold — by composing STT, LLM, and TTS into a single C++ pipeline on Apple Silicon. No cloud. No network. Just speed.

Wally

Wally hosted inference, local neural accelerators, and open-source SDKs from one inference lab.

Wally

  • Overview
  • Documentation
  • Console login

Developers

  • NeuRT
  • QHexRT
  • Local SDKs
  • GitHub

Research

  • Publications
  • Engineering blog
  • Inference Radar

Company

  • About
  • Press
  • Talk to us

© 2026 Wally, Inc.

  • Terms
  • Privacy
  • Refunds
  • Acceptable use